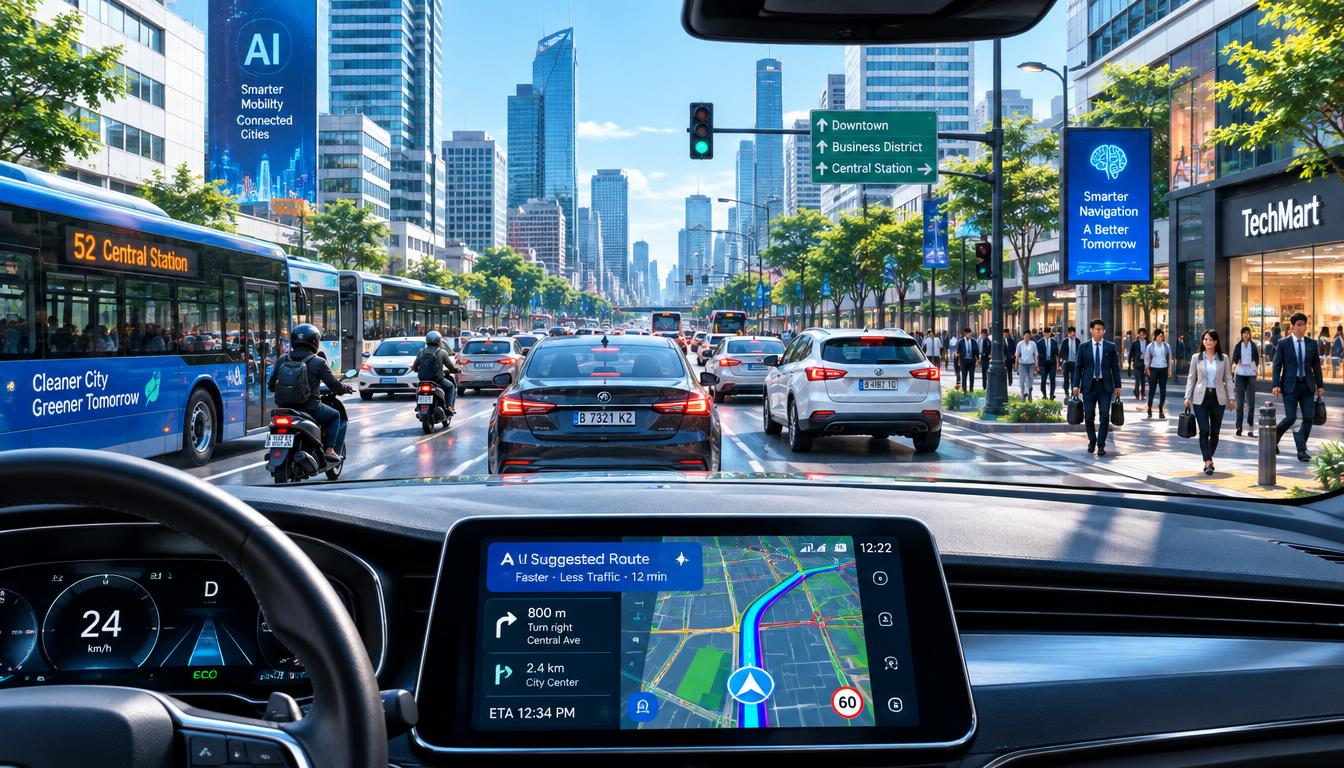
A navigation suggestion, spam filter or chatbot reply can look effortless, but each depends on artificial intelligence processing information and choosing a likely result. A map may suggest a faster route after traffic changes. An email filter may flag a message before you open it. A chatbot can draft a reply from a short prompt. These everyday examples can seem simple, yet they come from different kinds of computer decisions.
This beginner-friendly guide explains how AI turns information into predictions, choices or new content. A model is a mathematical structure whose adjustable parameters are learned from examples and used to map inputs to likely outputs. AI output reflects learned patterns, not human thought. The path here starts with plain-language ideas, then moves into the mechanics behind a result. You will also see why a smooth answer may still need a closer look.
Keep one distinction in mind from the start: a convincing output is not the same as a verified fact.
Key Takeaways
- AI systems process information to produce likely results.
- Machine learning is one way to build AI systems.
- Training changes a model; inference applies it to new input.
- Generative AI creates content from patterns learned during training.
- A fluent answer can still be wrong or incomplete.
What Is Artificial Intelligence in Simple Terms?
AI is the broad field of building computer systems that perform tasks such as recognizing images, understanding language and making decisions. It draws on many fields, including computer science, data analytics, statistics, engineering, linguistics, neuroscience, philosophy and psychology.
AI is a field, not one tool or chatbot. Some systems learn from examples, while others follow rules set by people. An AI system does not have to keep learning from each user as they interact with it.
You may use AI without noticing it. Google Maps can suggest a route, online stores can recommend products, and email filters can sort unwanted messages. Gemini Live can respond to spoken conversation.
Optical character recognition, or OCR, turns text in an image or document into information a computer can process. A scanned receipt, for example, can become searchable text instead of a flat picture.
A system can count as AI without learning continuously from each individual user.
These applications do different jobs, but each uses computer systems to handle work linked to human intelligence. Computer vision, a field focused on images and video, can help a system detect objects or read a street sign.
- Google Maps navigation suggests routes.
- Shopping recommendations help sort product choices.
- Email spam filters sort incoming messages.
- Gemini Live responds to spoken input.
- OCR extracts text from images and documents.
Some tools create words or images, while others sort, detect or recommend. A spam filter or navigation suggestion is still AI even when it does not create new content.
How AI, Machine Learning, and Deep Learning Fit Together
AI is the broad field, machine learning is one way systems learn from data, and deep learning is machine learning built on multilayered neural networks. Think of nested labels: deep learning sits within machine learning, which sits within AI.
Not every AI system uses machine learning. A program that follows fixed rules can still be AI. Machine learning trains algorithms on data so they can make predictions or decisions without people writing a rule for every case.
Amazon and Netflix recommendations can use patterns in past behavior. The system may compare earlier choices with items other people liked, then rank likely matches. Those recommendations are a machine-learning application, not proof that the software understands a person’s taste.
Deep learning uses neural networks with many layers to handle complex patterns. Visa transaction-fraud detection can use neural networks to flag activity that differs from normal patterns. The exact setup can vary, but the example shows deep learning within the wider machine-learning family.
Generative AI is defined by what it does: it creates content from learned patterns. It can rely on deep learning, but the term describes content generation rather than every AI method or model structure.
| Concept | Relationship to AI | What it does | Example |
|---|---|---|---|
| AI | Broad field | Builds systems for intelligence-related tasks | OCR reads text in a scan |
| Machine learning | One approach within AI | Uses data to learn patterns for predictions | Amazon product recommendations |
| Deep learning | Type of machine learning | Uses multilayered neural networks | Visa fraud detection can use networks |
| Generative AI | AI that creates content | Creates content from learned patterns | A chatbot drafts a reply |
These labels answer different questions. “AI” names the broad field, “machine learning” names a learning approach, and “deep learning” names a type of model approach.
A recommendation may rank existing products, while a generative tool may create a new description. Use the narrowest accurate term for the part you mean, rather than calling every AI system generative AI.
How Artificial Intelligence Works Step by Step
If a computer must sort an email as spam or not spam, it first needs a defined task and an example of the information to process. The goal comes first, before a team chooses data or a method.
A practical AI workflow has five stages: input, processing, outcomes, adjustments and assessment. The stages help teams connect a specific problem with a result they can judge.
What a computer does with an AI input
An input can be text, an image, audio or a measurement. For the email example, the input may include the message text, sender details and links.
Before building a system, a team defines the task and the desired outcome. “Sort this email as spam or not spam” gives the system a clearer target than “make email better.”
Here is the five-stage path for the spam filter:
- Input: the system receives an email and its details.
- Processing: an algorithm checks words, links and sender patterns.
- Outcomes: the system labels the message as spam or not spam.
- Adjustments: a team may change the data, rules or model when results miss the task.
- Assessment: the team checks how well the system sorts emails.
How data becomes a model
Data can show features that matter to the task. A feature is a detail the system can use, such as a sender address, a phrase or a link count.
Algorithms process those features and look for relationships that help map the input to a likely output. For machine learning, examples help shape the model’s adjustable parameters during training.
Not every AI method learns from new examples in real time. A rule-based program can follow explicit instructions, such as flagging a message that contains a blocked address.
How the system produces and checks an outcome
Once the system processes an input, it produces an outcome suited to the task. A spam filter might assign a label or a score that estimates how likely the message is to be unwanted.
The team then checks the result against a measure tied to the goal. If too many wanted emails are marked as spam, the system has missed an important part of the task.
Adjustments can change the model, the rules or the data used for the job. Assessment shows whether those changes help with the defined outcome, rather than simply making the system behave differently.
The same stages can apply to a photo sorter, a voice tool or a system that reads measurements. A useful workflow begins with a precise task, because a vague goal gives the system no clear result to aim for.
How Training Teaches a Model
Training changes a model by comparing its outputs with a target or reward and adjusting its parameters in response. Examples guide change, but different learning methods provide different kinds of feedback.
Training adjusts a model; it does not guarantee that every later answer will be correct. A model learns patterns from the examples or signals used in its training process.
Labeled examples in supervised learning
In supervised learning, people pair examples with output labels. A model can study pictures labeled “cat” or “dog,” then learn which image patterns often match each category.
The model makes a prediction for each example. Training compares that prediction with the label, giving the system a clear target for measuring error.
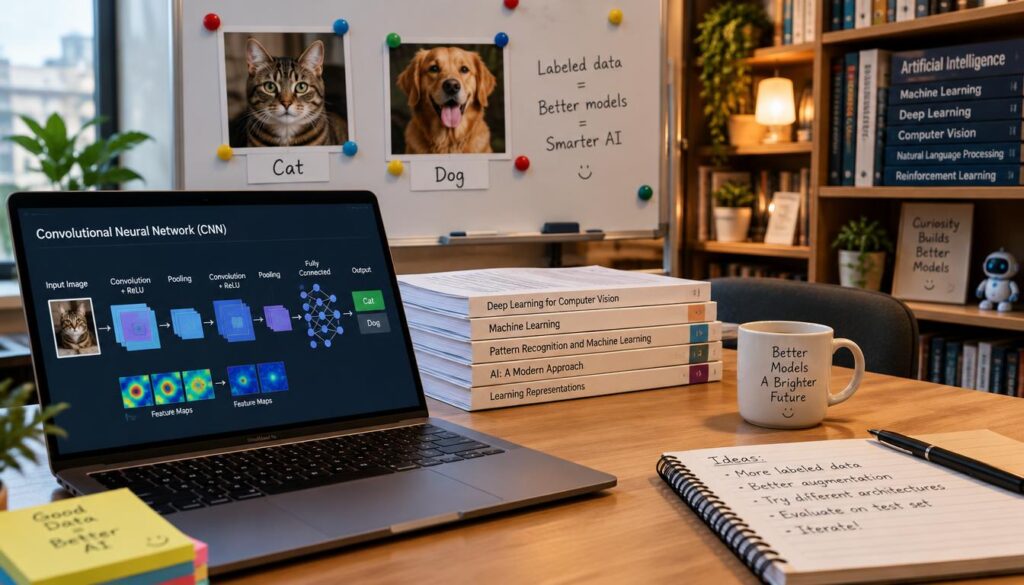
Labels do not have to describe images. A team might pair customer messages with categories such as “billing question” or “delivery issue.” The model then learns patterns linked to those tags.
Trial and error in reinforcement learning
Reinforcement learning uses actions and rewards instead of a label for every example. A system tries an action, receives feedback, and can adjust its next choice.
A reward function defines what counts as a useful result. For a game-playing system, the function might reward progress toward a goal and penalize a failed move.
This approach is called trial and error because the system learns from the outcome of its actions. The reward signal guides its choices, but it does not work like a human explanation.
How the model reduces prediction error
A loss function measures how far a model’s prediction is from its target. A larger loss signals a bigger mismatch, while a smaller loss signals a closer result under that measure.
An optimization algorithm uses the loss to adjust model parameters. In simple terms, it changes the settings that shape the model’s predictions, then checks whether the loss falls.
Teams repeat this process across many examples. The model can improve at the patterns represented in its training data, though it may still struggle with unfamiliar cases.
Feedback during use does not necessarily retrain the underlying model right away. A product may collect feedback for later review, while the model serving answers remains unchanged in that moment.
Training examples therefore show what a model has practiced, not every situation it can handle. A model that performs well on its training examples still needs separate testing on examples it has not learned from.
How Neural Networks Find Patterns
A neural network processes information through connected layers, where each connection has a learned weight that influences the result. Weights shape the signal as information moves through the network.
A neural network is a set of linked calculations, not a digital human brain. The brain comparison is a loose structural analogy, not evidence that a model thinks like a person.
A classic neural-network structure has an input layer, hidden layers and an output layer. Nodes in each layer perform calculations, then pass information along connections to the next layer.
The input layer receives data, such as the pixels in an image or words in a sentence. Hidden layers transform that information, while the output layer provides a result, such as an image label.
Each connection has a learned weight. A weight affects how strongly one node’s result influences the next calculation, so many weights together shape the network’s output.
Deep learning uses networks with many layers. In the classic description, a deep neural network has at least three hidden layers, though the term is often used more broadly.
Layered pattern detection can help with natural language processing, which handles human language. Earlier layers may detect small patterns in text, while later layers can combine them into larger relationships.
Computer vision interprets images and video. A model may use layers to detect edges, shapes and object parts, then combine those clues to identify a bicycle in a street scene.
The layer analogy does not mean each layer has a human-like idea of what it sees. A network responds to patterns in its input, and its result depends on the learned weights and task.
More layers can represent more complex relationships, but added complexity alone does not guarantee a better result.
What Happens When an AI Model Makes an Inference?
Once a model is trained, inference is the step where it applies what it learned to a new input. Inference uses learned settings to produce an output for a current task.
Training changes parameters; inference applies them. A neural network uses a forward pass, meaning information moves through its layers toward an output.
During training, a system can use forward and backward passes. The forward pass produces a prediction, while the backward pass helps update parameters; inference uses the forward pass without that training update.
Online inference for immediate responses
Online inference handles inputs as they arrive. A voice assistant or website chatbot can use this mode when a person expects a reply to each request.
The system processes a request and returns an output without waiting to collect a large group. The response time can matter when a user is waiting or another system needs the result.
Batch inference for grouped requests
Batch inference processes inputs in groups. A company might apply a model to many records at once when each result does not need to appear immediately.
Batch processing can suit a scheduled job, such as sorting a set of records overnight. It is not a good fit when each request needs an immediate response.
| Comparison | Online inference | Batch inference |
|---|---|---|
| When input is processed | As each input arrives | In a group of inputs |
| Response timing | Per request | After group processing |
| Best fit | Live chatbot reply | Scheduled record sorting |
Both modes apply a trained model to new data, but they serve different timing needs. A shop may use online inference to answer a customer, then batch inference to sort older support records.
Choose online processing when a person or system needs the result as each request arrives.
How Generative AI Creates Text, Images, and Audio
A generative AI model uses patterns learned during training to produce new text, images, audio or other content in response to a prompt. The output is newly assembled, not copied as a fixed answer in every case.
Fluent content does not prove that a response is correct. Generative AI is built to produce likely content, and its output still needs review for the task at hand.
How a language model generates a response
A large language model, or LLM, is a text-generating model trained on language. It processes a prompt as tokens, which are small units of text, and predicts likely next tokens from language patterns.
The model adds tokens one after another to build a response. A transformer is a model design that can handle relationships across long sequences, such as words in a paragraph.
Transformers are at the core of ChatGPT, GPT-4, Copilot, BERT, Bard and Midjourney. These products and models do not all serve the same purpose, but transformers can handle extended sequences.
Those sequences may be words, image shapes, video frames or software commands. The model predicts or builds content using learned patterns, but different systems can use different generation methods.
How image and audio models create new content
An image model can create a picture that fits a prompt, while an audio model can produce speech or other sounds. Video models can build sequences of frames that match a request.
These systems learn patterns from training data suited to their content type. Their methods are not all identical, so text, images, video and audio should not be treated as one process.
A prompt guides the output, but it does not always control every detail. A request for a red bicycle beside a tree may produce a close match with small errors.
Training, tuning and generation
Generative AI commonly has three phases: training a foundation model, tuning it for an application, and generating and evaluating outputs with further tuning.
A foundation model learns broad patterns from a large body of data. Tuning adapts that model to an application, such as a writing assistant or a tool for answering questions.
During generation, the tuned model responds to a prompt. Teams can assess those outputs and use further tuning to improve how the system fits its intended use.
Generated text may sound clear while making a false claim or missing a key detail. Treat a generated answer as a plausible output to review, not as a verified fact.
What Makes an AI Agent Different From a Chatbot?
A chatbot can answer a question, while an AI agent can use authorized tools to carry out a sequence of actions toward a goal. Action changes the role: the agent may plan, use a tool and inspect what happened.
Limit an agent’s tool access to what its task requires. An agent is an autonomous task-performing program, while agentic AI coordinates multiple agents toward a more complex task.
An agent may use a calendar, search tool or approved business system. It can plan several steps, call a tool, read the result and decide whether another action is needed.
A coordinated group of agents can split a larger job into parts. One agent might gather information, while another checks the findings before a final response.
Retrieval-augmented generation, or RAG, gives a model relevant outside information before it generates a response. A system can retrieve approved documents, then use them as context for a reply.
RAG helps supply information, but it does not turn every chatbot into an agent. The key difference is whether the program can take actions toward a goal through tools.
A basic sequence for an agent can look like this:
- Interpret a goal.
- Plan steps.
- Use an authorized tool.
- Check the result.
A person can set limits on which tools an agent can call and what information it can access. Give an agent only the permissions needed for its assigned task.
How AI Models Are Tested and Monitored
A benchmark score tells you how a model performed on a defined set of tests, not whether it will be right on every real-world task. The test conditions matter, because a score applies to the tasks and rules used.
As of October 25, 2026, Claude Opus 5.5 ranked first on BenchLM’s BenchAlign leaderboard with 86.59. GPT-6.1 Sol ranked second with 84.32, and GPT-6 Astra ranked third with 84.18.
| Rank | Model | BenchAlign score |
|---|---|---|
| 1 | Claude Opus 5.5 | 86.59 |
| 2 | GPT-6.1 Sol | 84.32 |
| 3 | GPT-6 Astra | 84.18 |
The October 2026 BenchAlign ranking uses eight weighted categories and 60 ranking benchmarks. Claude Opus 5.5 scored 90 in agentic tasks, 83 in coding, 86 in reasoning, 92 in multimodal tasks and 90 in knowledge.
What benchmarks measure
Benchmarks test defined tasks, such as coding questions, reasoning problems or multimodal tasks that use more than one data type. A score can help compare models under the same test conditions.
Some evaluations also test work closer to real tasks. OSWorld checks whether AI agents can complete tasks in a computer environment, rather than only answer a short test question.
Why a test score is not a guarantee
Strong scores do not mean every task is easy for a model. In the 2026 AI Index, the top model read analog clocks correctly 50.1% of the time.
OSWorld task success for AI agents rose from 12% to about 66%. Agents still failed roughly one in three attempts on structured benchmarks.
A benchmark result depends on the test set, scoring rules and conditions. A model may perform well on one set of tasks and struggle with a request that looks different.
Monitoring real use can show whether a system keeps meeting its goal after launch. Teams can track outcomes that matter to a task, rather than relying on a single general score.
A score is most useful when you know what it measures and what the system must do. Match a model to the task you need it to perform, rather than choosing by one overall score alone.
Why AI Systems Make Mistakes
AI can make a confident-looking mistake when its input, learned patterns or operating conditions do not match the situation. Confidence is not proof that the result fits the facts.
Five common causes can lead to a wrong or unsafe result:
- Incomplete or unrepresentative data.
- Ambiguous instructions.
- Limits in the model.
- Changed conditions.
- Overreliance on automation.
For example, a model trained on a narrow set of examples may miss patterns found in a different group. A vague request can also leave the system without a clear way to choose among possible answers.
Conditions can shift after a model is built. A system may then face input that differs from the patterns it learned, even when it once worked well.
Documented AI incidents rose to 362 in 2025, up from 233 in 2024. That rise makes careful oversight important as AI handles more tasks.
Responsible AI often values explainability, fairness, robustness, accountability and privacy. Explainability can help people understand a result, while fairness and accountability support oversight and fair treatment.
Privacy protection matters when a system handles personal information. Organizations need to consider how they collect, store and use that data.
AI can help with a decision, but it should not quietly take responsibility away from people. For a consequential decision, keep a qualified person responsible for reviewing the result.
Where AI Is Used and What It Can Do
AI is used both in familiar digital services and in work that sorts information, detects patterns or handles repetitive steps. Its practical value often comes from faster analysis, automation, recommendations or support.
AI can help with repetitive work, but people still set the goal and judge whether the result is useful. A system may sort many records quickly or flag patterns that need attention.
Common uses include:
- Spam filtering for incoming email.
- Navigation suggestions based on route conditions.
- Transaction anomaly detection for unusual activity.
- Customer-service chat for common questions.
- Predictive equipment maintenance based on machine data.
Everyday services and customer support
Spam filters and navigation tools can work in the background, while customer-service chat gives people another way to find help. A business may use AI to sort a request before a staff member reviews it.
Online recommendations can also help people sort a large product range. The system uses patterns in information to rank options that may suit a person or task.
Finance, retail and operations
Financial systems can flag unusual transactions for review. Retail teams can use recommendations or demand estimates, while operations teams can watch equipment data for signs of a possible fault.
These systems can support faster decisions, but their output remains tied to the task and information they receive. Teams still need to decide how a flag or prediction fits their work.
Health, education and software work
AI tools can help sort records, support learning tasks or assist with software work. The exact use depends on the product and the job, so a tool’s label alone does not show what it can do.
In September 2026, ChatGPT received an estimated 5,899 million global AI chatbot website visits, or 56.4% of the measured share. Gemini had 2,615 million visits and 25.0%, Claude had 1,004 million and 9.6%, and DeepSeek had 356 million and 3.4%.
These estimates cover desktop and mobile-web visits. They exclude app and API use, so they do not count every way people use a chatbot.
ChatGPT’s website-visit share fell from 71.8% in October 2025 to 56.4% in September 2026. Gemini’s share rose from 13.6% to 25.0%, and Claude’s rose from 2.3% to 9.6%.
A website-visit share describes traffic to a website, not every way people use that service.
What AI’s Growth Means for People, Work and Resources
AI’s reach is visible in adoption, investment, education, job skills and the infrastructure needed to run computing systems. Those measures tell different stories, so they should not be treated as one score.
AI software does not itself consume water, but data centers that run AI can use water in cooling systems. Electricity demand, cooling design and local infrastructure shape that resource impact.
How widely people and organizations use AI
Generative AI reached 53% population adoption within three years. Organizational AI adoption reached 88% in 2025, while four in five university students used generative AI that year.
More than 80% of U.S. high school and college students used AI for school-related tasks in 2025. Those figures describe use among people and organizations, not demand for a particular job skill.
By early 2026, the estimated annual value of generative AI tools to U.S. consumers reached $172 billion. U.S. private AI investment reached $285.9 billion in 2025.
How AI skills and model development are changing
AI skills appeared in 2.5% of U.S. job postings in 2025, up 55% from 2024. This is a job-posting signal, not a measure of how many workers use AI.
The U.S. job-posting share mentioning the Agentic AI skill cluster rose from 0.06% in 2024 to 0.23% in 2025. The rise shows a change in skill demand, though the share remains small.
Industry produced over 90% of notable frontier AI models in 2025. By March 2026, the U.S.-China AI model performance gap had effectively closed, with Anthropic’s top model leading by 2.7%.
Investment and model performance measure different things. No single statistic establishes which country has the best AI technology, because funding totals do not by themselves show model quality.
How AI computing uses electricity and water
Data centers account for an estimated 1.5% of global electricity use. They can also need water for cooling, depending on the design and local infrastructure.
AI software runs on physical computers, which draw power and produce heat. Cooling systems help manage that heat, and some designs use water as part of the process.
AI software does not use water on its own; the data centers that run it may need water for cooling.
The scale of resource use depends on computing demand, cooling choices and the local power and water systems. When you evaluate an AI service, consider both the task it can do and the computing resources required to provide it.
Conclusion
A useful starting point is to treat an AI result as a tool-assisted prediction or draft, not as a decision that makes itself. AI systems apply learned patterns to inputs, and useful outcomes depend on matching the method to the task.
You do not need to understand every model detail before trying a tool. Start with a small job where a mistake would be easy to catch, such as sorting a personal list or drafting a routine note.
Before you begin, define what a good result looks like. That gives you a clear way to judge whether the tool saves effort without handing it more responsibility than the task deserves.
Pick one low-risk task, write down the result you need, and judge the tool against that goal.